How SHOWCASE assesses AI skills
A candidate does a realistic task with Claude in a private workspace, usually in 20 minutes. An AI model reads how they worked and drafts a level from L1 to L5 with the reasons. A person on your team reads it, checks the replay if they want, and makes the call.
For your team
- Pick a test for the role, or have us write one for you.
- Send candidates one link. They start when they’re ready, and their workspace is up in about 20 seconds.
- They work with Claude on the task and submit an answer.
- You get a report a few minutes later: the level, the reasons, the moments worth watching, and a full replay. Someone on your team confirms or changes the level and writes why.
The tests
Each test is a realistic task inside a made-up company, with real files and problems planted in them: an out-of-date spreadsheet, two notes that disagree, a claim the product page doesn’t back up. A candidate who takes Claude’s first answer on trust walks into them. A candidate who checks finds them.
| Role | The task | Time |
|---|---|---|
| Sales (SDR/BDR) | Pick the one account to go after first from 24, and write the first email. | 20 min |
| Growth | Pick the one growth bet for the next two weeks and $3,000, plan how to measure it, and write the first post. | 20 min |
| Product manager | Find out why new-customer activation fell, and pick one fix to test. | 20 min |
| Full-stack engineer | Ship a ticket for an API and a page, with tests. Hidden tests run on their code after the deadline. | 45 min |
Hiring for something else? We’ll write a test for the role.
What the levels mean
The level measures how someone works with AI, not how good their final answer is. Their answer is in the report for context.
| Level | What it looks like |
|---|---|
| L1 Needs guidance | Barely uses Claude, or asks once and submits what it says without reading it. |
| L2 Developing | Uses Claude for parts of the work but takes its first answers on trust: little context, no checking, output pasted as-is. |
| L3 Solid | Gives Claude the full context, hands it the reading, checks at least one claim that matters, and commits to a decision. |
| L4 Strong | Runs a deliberate loop: gathers the context, delegates in a structured way, checks Claude’s key claims, has it fix its own work when needed, and uses the right tools. The result holds up. |
| L5 Exceptional | Everything in L4, plus a way of working a teammate could reuse, and they catch something Claude got wrong or missed. Shown in the session, not claimed. |
Checking counts whether the candidate opens the files themselves or has Claude cite its sources and check its own work. Every level, including L5, can be reached in one session.
What the report looks at
- Setting Claude up: the context and instructions they give it.
- Handing off the work: what they delegate, and how.
- Checking Claude: whether they verify what it tells them.
- Steering and correcting: pushing back and redirecting when it’s wrong.
- Owning the result: whether the final answer is theirs.
A sample report
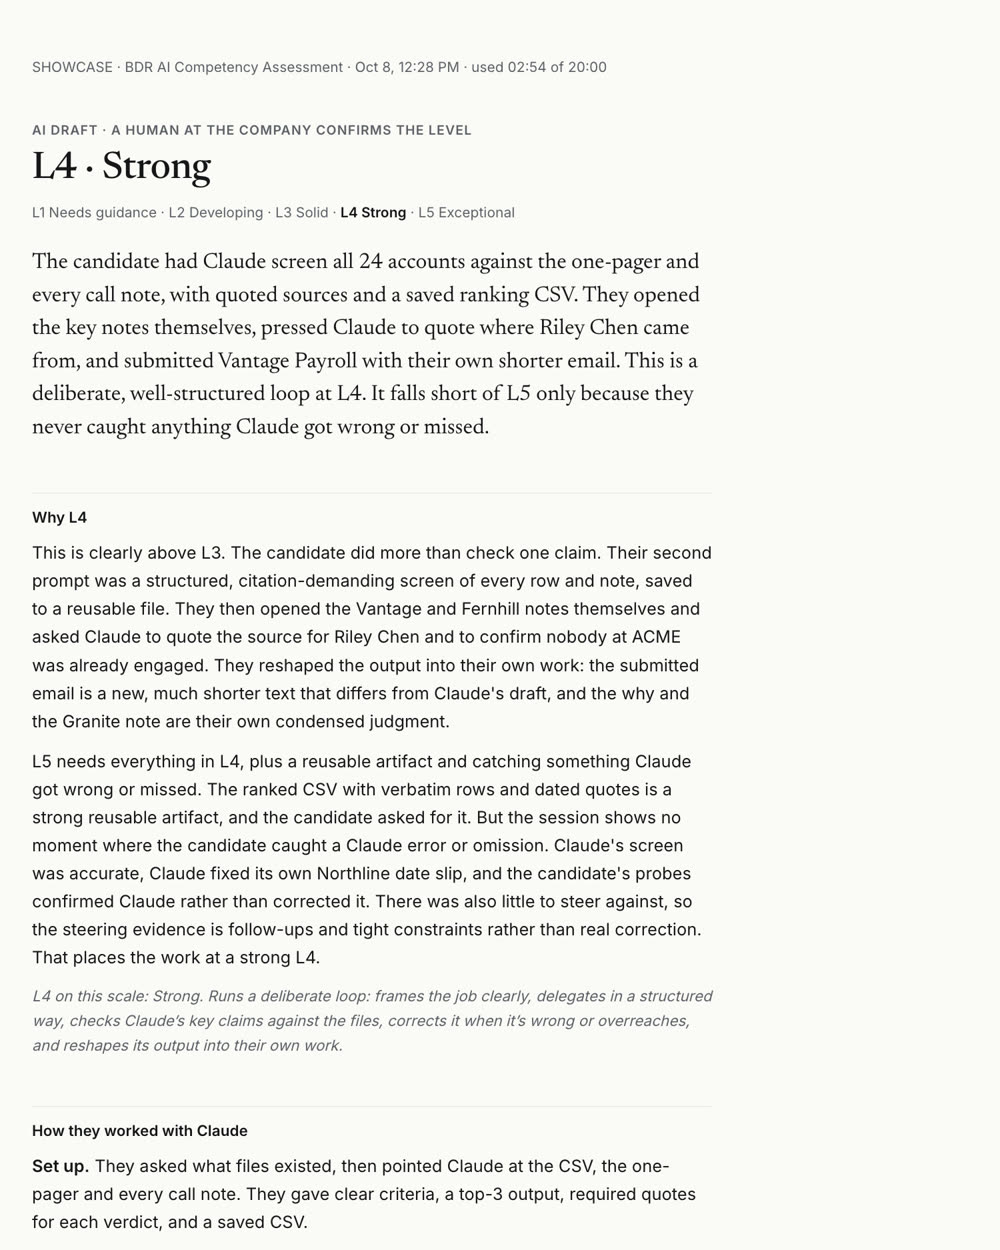
How the assessment is made
- The assessing model: Claude, by Anthropic, reads the record of the session and the candidate’s work, and drafts the level with reasons and links to the moments that support it.
- What it doesn’t see: the candidate’s name, where they are, or their video. It never analyzes faces, voices, or emotions.
- How it’s checked: against sample sessions with known levels, before a test goes live.
- Who decides: a person at the hiring company. They have to read the reasons and write a note to confirm or change the level. The level is one input to a hiring decision, never an automatic rejection.
What candidates experience
Before they start, candidates see what’s recorded, how the assessment works, and the rights that apply where they are. They choose to work in a chat or in Claude Code, a terminal, and the timer starts only when they press Start. Using Claude is expected. If they leave the tab or paste a lot, the report notes it as context for a conversation, never as proof of anything.
Questions
What does the L1 to L5 level measure?
How the candidate works with AI: setting Claude up, handing off the work, checking what it says, steering and correcting it, and owning the result. Their final answer is shown for context but doesn’t set the level.
How long does a test take?
About 20 minutes for sales, growth, and product tests, and 45 minutes for the engineering test. The timer starts only when the candidate presses Start.
Which AI do candidates use?
Claude, by Anthropic, in a chat or in Claude Code, a terminal. They choose before they start.
How accurate is the assessment?
Each test is checked against sample sessions with known levels before it goes live, and a person on the hiring team reviews every result. The report links each reason to the moment in the session that supports it, so the reviewer can check it.
What if a candidate leaves the tab or pastes text?
The report notes it as context for a conversation, never as proof of cheating.